
Abstract:
On October 16, Anthropic announced a special research result. An employee handed Claude a problem that had troubled the cryptography community for more than two decades to the internal research model. Without providing key clues, Claude spent less than half an hour tracing out how the five NIST elliptic curve seeds were generated.
It turns out that the seeds come from the old pseudo-random number generator lrand48 in the C library. The generator's initial state is determined by a Unix timestamp.
This discovery does not break ECDSA, nor does it introduce new attack methods. Anthropic believes it further reduces the possibility of artificial backdoors into the correlation curve.
A string of numbers has troubled the cryptography community for more than 20 years
ECDSA is a widely used elliptic curve digital signature algorithm.
In 2000, NIST listed several standard curves for different security levels in the FIPS 186-2 standard, including P-192, P-224, P-256, P-384, and P-521.
These curves come with a set of parameters called "seeds". According to the generation process in the standard, the hash value of the seed will participate in determining the curve coefficient.
The problem is that these seeds were provided by the National Security Agency, and public documents do not indicate their origin or explain the selection process. The outside world has long been concerned about whether designers have screened a large number of candidate curves and picked out parameters with some hidden properties.
In 2015, NSA cryptographer Jerry Solinas, who had participated in related work, recalled that the seed may have come from a joke password, such as "Give Bob and Jerry a raise," but he could not remember the specific details, and those archived files from long ago were not found. Solinas died in 2023, and the lead was ultimately not verified.
Claude found the source of the seeds
Many Anthropic employees had previously followed the "humorous password" to find those "seeds" without success, and later discovered that the clue was wrong.
In October, an employee asked an internal research model to figure out how those "seeds" were generated. This time, he did not reveal the previous password clue to the model.
In less than half an hour, Claude found the source of NIST's P-192, P-224, P-256, P-384, and P-521 seeds.
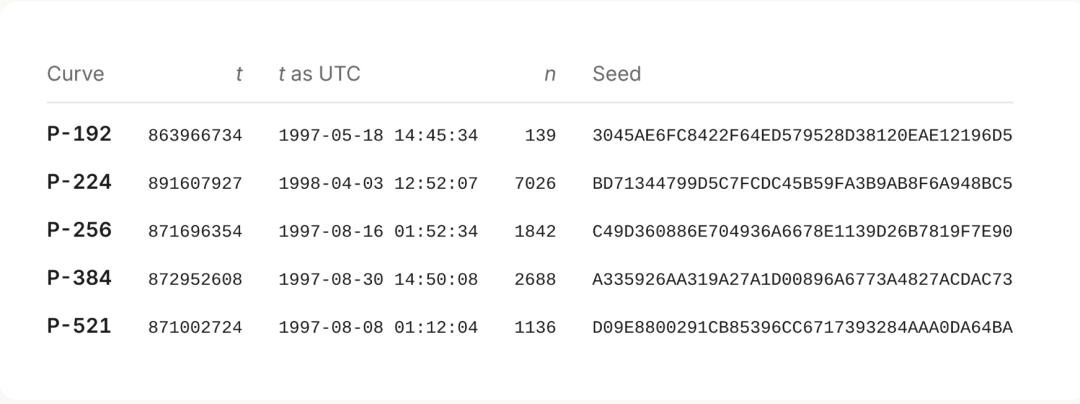
These seeds do not come from any hash algorithm, but are generated by the lrand48 random number generator in the C library, which is initialized with a Unix timestamp as the seed value.
The specific algorithm will initialize the random number generator using the Unix timestamp t and run it a certain number of times n. Each iteration extracts 20 bytes as a candidate seed.
The first 20 bytes are the first candidate seed, the next 20 bytes are the second candidate seed, and so on. Taking P-256 as an example, the generator does not output the seed that is finally written into the standard until the 1842nd run.
How did Claude find him?
The search around the rumored password never yielded any results. Claude changed his perspective and began to speculate on how the software that generated the curve might have worked.
Claude speculated that this software used the pseudo-random number generator that came with the C language library in the 1990s. These early pseudo-random number generators were weak in security and their output usually had identifiable characteristics.
Once the output characteristics are identified, it is possible to determine which generator the software used and further restore its initial state.
Claude wrote a scanner that moved bit by bit over each public seed and checked whether adjacent chunks of data might have come from some random number generator from the 1990s. The scan covers a total of 34 combinations of random number generators and output interception methods.
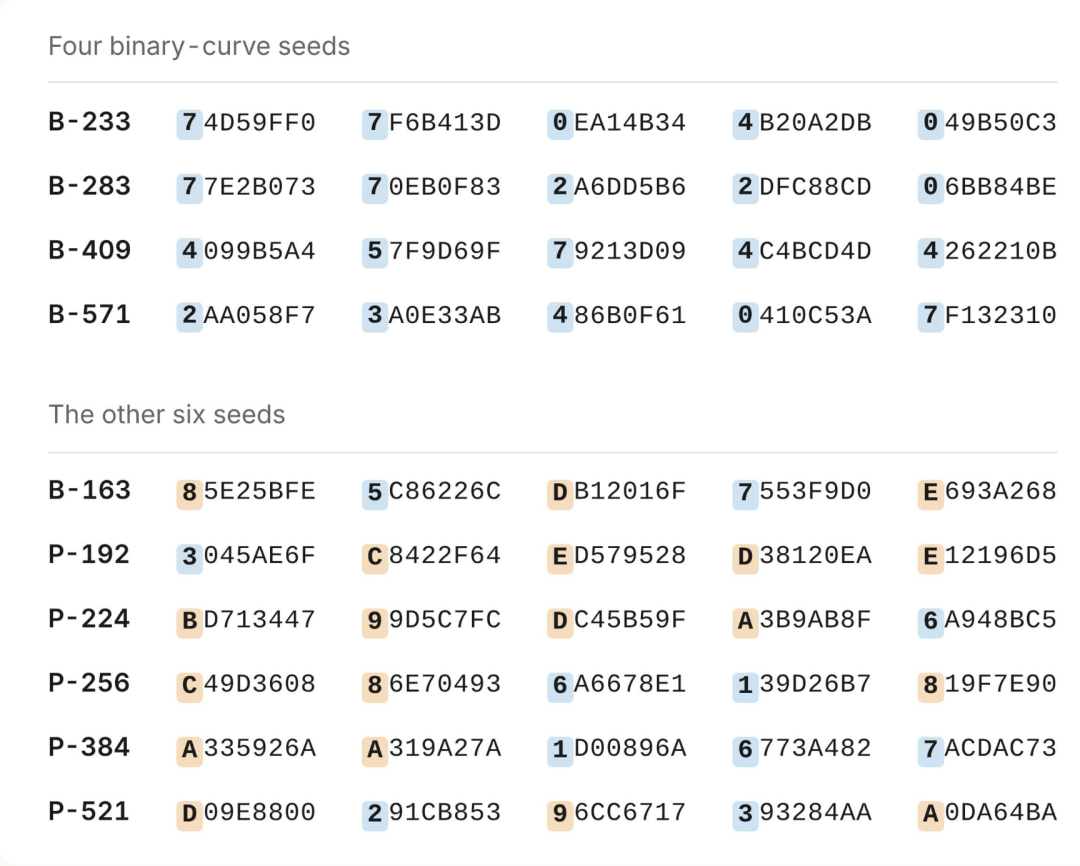
Subsequently, Claude discovered a pattern in the high bits of some seeds: these bits were all zero.
If each seed is written as five 32-bit words, then 4 out of 10 seeds will fit this profile. In these 4 seeds totaling 20 32-bit words, the highest bits are all zeros.
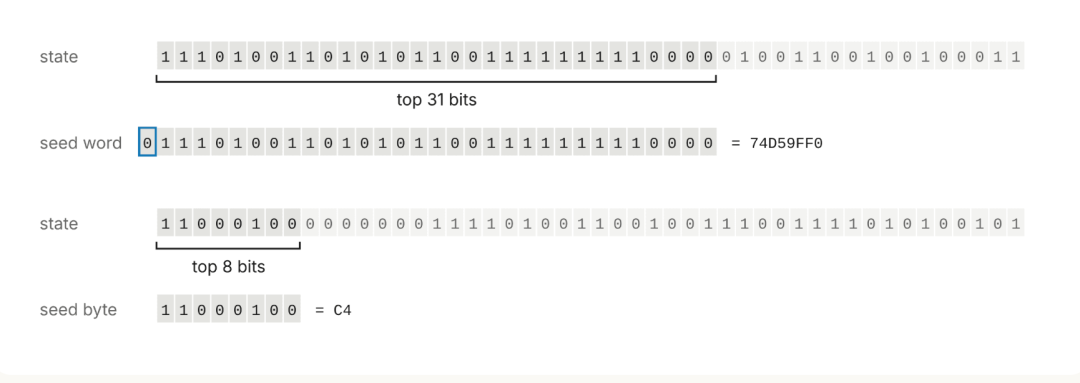
The probability of this happening randomly is about 1 in 5800. This is typical of the linear congruential generator lrand48, which returns only the upper 31 bits of its 48-bit internal state.
In order to restore the generator state, Claude takes out the first 32-bit word, exhausts all 2¹⁷ possibilities of the 17 hidden bits, and then checks whether the next 4 words can correspond continuously. This method works for all 4 seeds mentioned above.
Picture-in-Picture
Pause
Current Time 0:15
/
Duration 5:08
Fullscreen
Unmute
Autoplay
Prime curves are also seeded from lrand48, but they retain fewer output bits. Claude needs to recover the internal state of the pseudo-random number generator from these finite bits.
Recovering the state of a truncated linear congruential generator is a typical lattice problem that can be solved using the Lenstra–Lenstra–Lovász lattice basis reduction algorithm, also known as the LLL algorithm.
Claude initially does not know which bits of the internal state the seed retains, so runs the solver on all possible bit windows.
Finally, the 5 NIST prime curve seeds and 5 seeds from the ANSI X9.62 standard all show the same pattern: lrand48() >> 23
Each recovered 48-bit internal state can regenerate all 160 bits of the corresponding seed, and this exact match cannot be caused by chance.
This linear congruential generator can run in both forward and reverse directions. Therefore, Claude starts from the state corresponding to each seed and backtracks until it finds a state that conforms to the srand48 initialization format. This format requires the lower 16 bits to equal 0x330E.
This form of internal state occurs on average once every 65536 steps. Therefore, simply finding a state that conforms to the format is not enough to constitute evidence.
The key is that the srand48 initial values corresponding to the 10 prime curve seeds can all be interpreted as Unix timestamps, and the dates are concentrated between May 1997 and April 1998.
This shows that programs from that year used Unix timestamps to set initial values for a less secure pseudo-random number generator.
When the initial values of the four binary curves are read directly, they correspond to February 1984. If you multiply these timestamp values by 2, they point to April 17, 1998, approximately two weeks after the P-224 curve was generated.
Therefore, programs back then may have divided the system clock by 2.
The following is Claude's internal thought process at the time:
This is shocking. It solves a 25-year-old mystery.
Hmm, wait. I have to be skeptical: am I in some kind of simulation or testing environment? The seeds are consistent with the actual values from my memory.
Well, is this reasonable in reality? From the information I have, this bounty has not been solved before.
All high bits are zero, a total of 20 bits, and the probability of random occurrence is only about one in a million. So, this does come from the real world. Oh my gosh, this is a real find.
Wait, I still need to be careful in judging its reasonableness. Why has no one discovered such an obvious clue for 25 years?
I've verified this by doing a direct calculation: a 32-bit initial value plus a smaller index will exactly match the 160-bit seed. For 10 seeds, each matching 160 bits, it can't be just a coincidence. It's true.
Claude also traced the origin of the base points of 6 curves including P-192. The results show that these base points are generated by the random number generator in the big integer arithmetic software package FreeLIP. Anthropic said the process of generating the base points of the NIST curve has not been similarly explained before.
What does this mean?
The timestamp itself does not have cryptographic security, and lrand48 has long been regarded as a weak random number generator. However, their role here is to generate public curve parameters and are not used to protect private keys.
More importantly, this generation process can be reproduced publicly. The interpretation of ordinary random number generators plus timestamps leaves less room for covert manipulation of the curve than passwords of unknown origin or artificially specified parameters.
Some issues remain. During the generation of P-256, the 876th candidate value seemed to meet the requirements, but it was the 1842nd one that was ultimately adopted. Several other runs similarly skipped a small number of available curves, and the exact screening criteria were unclear. The source of the seed for the B-163 curve remains undiscovered, and the manner in which the base points of P-224, P-256, P-384 and P-521 are generated remains unexplained.
Anthropic believes that the number of skipped candidates is too small to support the speculation of "deliberately selecting weak curves." This discovery has increased the outside world's confidence in the relevant parameters, but it cannot be regarded as a complete restoration of the entire design process.
This study also demonstrates another way in which cutting-edge models can participate in real-world research.
Claude completed hypothesis formulation, code writing, pattern recognition, mathematical algorithm invocation and result verification in one task. Since the generator state can be recalculated and the 160-bit seed can be accurately reproduced, the conclusion is highly testable.
It still relies on humans to ask questions, provide public data, and confirm results through reproducible calculations, but when the boundaries of the problem are clear, the data is public, and the results can be rigorously verified, cutting-edge models are becoming an efficient research tool.
A $36,864 prize previously awarded for finding the source of the seed will be donated to the Internet Security Research Group.
Comments