
Abstract:
Google today officially announced its latest breakthrough in the field of native end-to-end voice interaction, launching a new generation of real-time voice large model Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking customized for difficult tasks.
These two models represent a major leap forward in Google's native audio-to-audio technology system. They not only push real-time conversation delay and naturalness to new heights, but also achieve deep multi-step reasoning capabilities in low-latency voice streams for the first time, completely changing the application paradigm of voice AI in complex professional scenarios.
In the previous mainstream voice interaction architecture, AI systems usually needed to make a compromise between "quick-response shallow dialogue" and "long-term deep thinking". Facing difficult problems often required users to endure long periods of silent waiting. Gemini 3.8 Live launched by Google focuses on optimizing the ultra-fast conversation and daily streaming interaction experience. It can provide users with extremely smooth and human-level real-time voice communication with more sensitive intonation fluctuations, natural interruptions and context understanding capabilities. Gemini 3.8 Live Extended Thinking, launched on its basis, has been fundamentally upgraded for highly complex business flows. This model gives AI the ability to "think as it speaks" (Think as it speaks) in the background, allowing the system to concurrently perform complex multi-step logic disassembly, code debugging or technical diagnosis in the background while maintaining a real-time coherent dialogue, without the need to abruptly interrupt the conversation rhythm when encountering difficult problems.
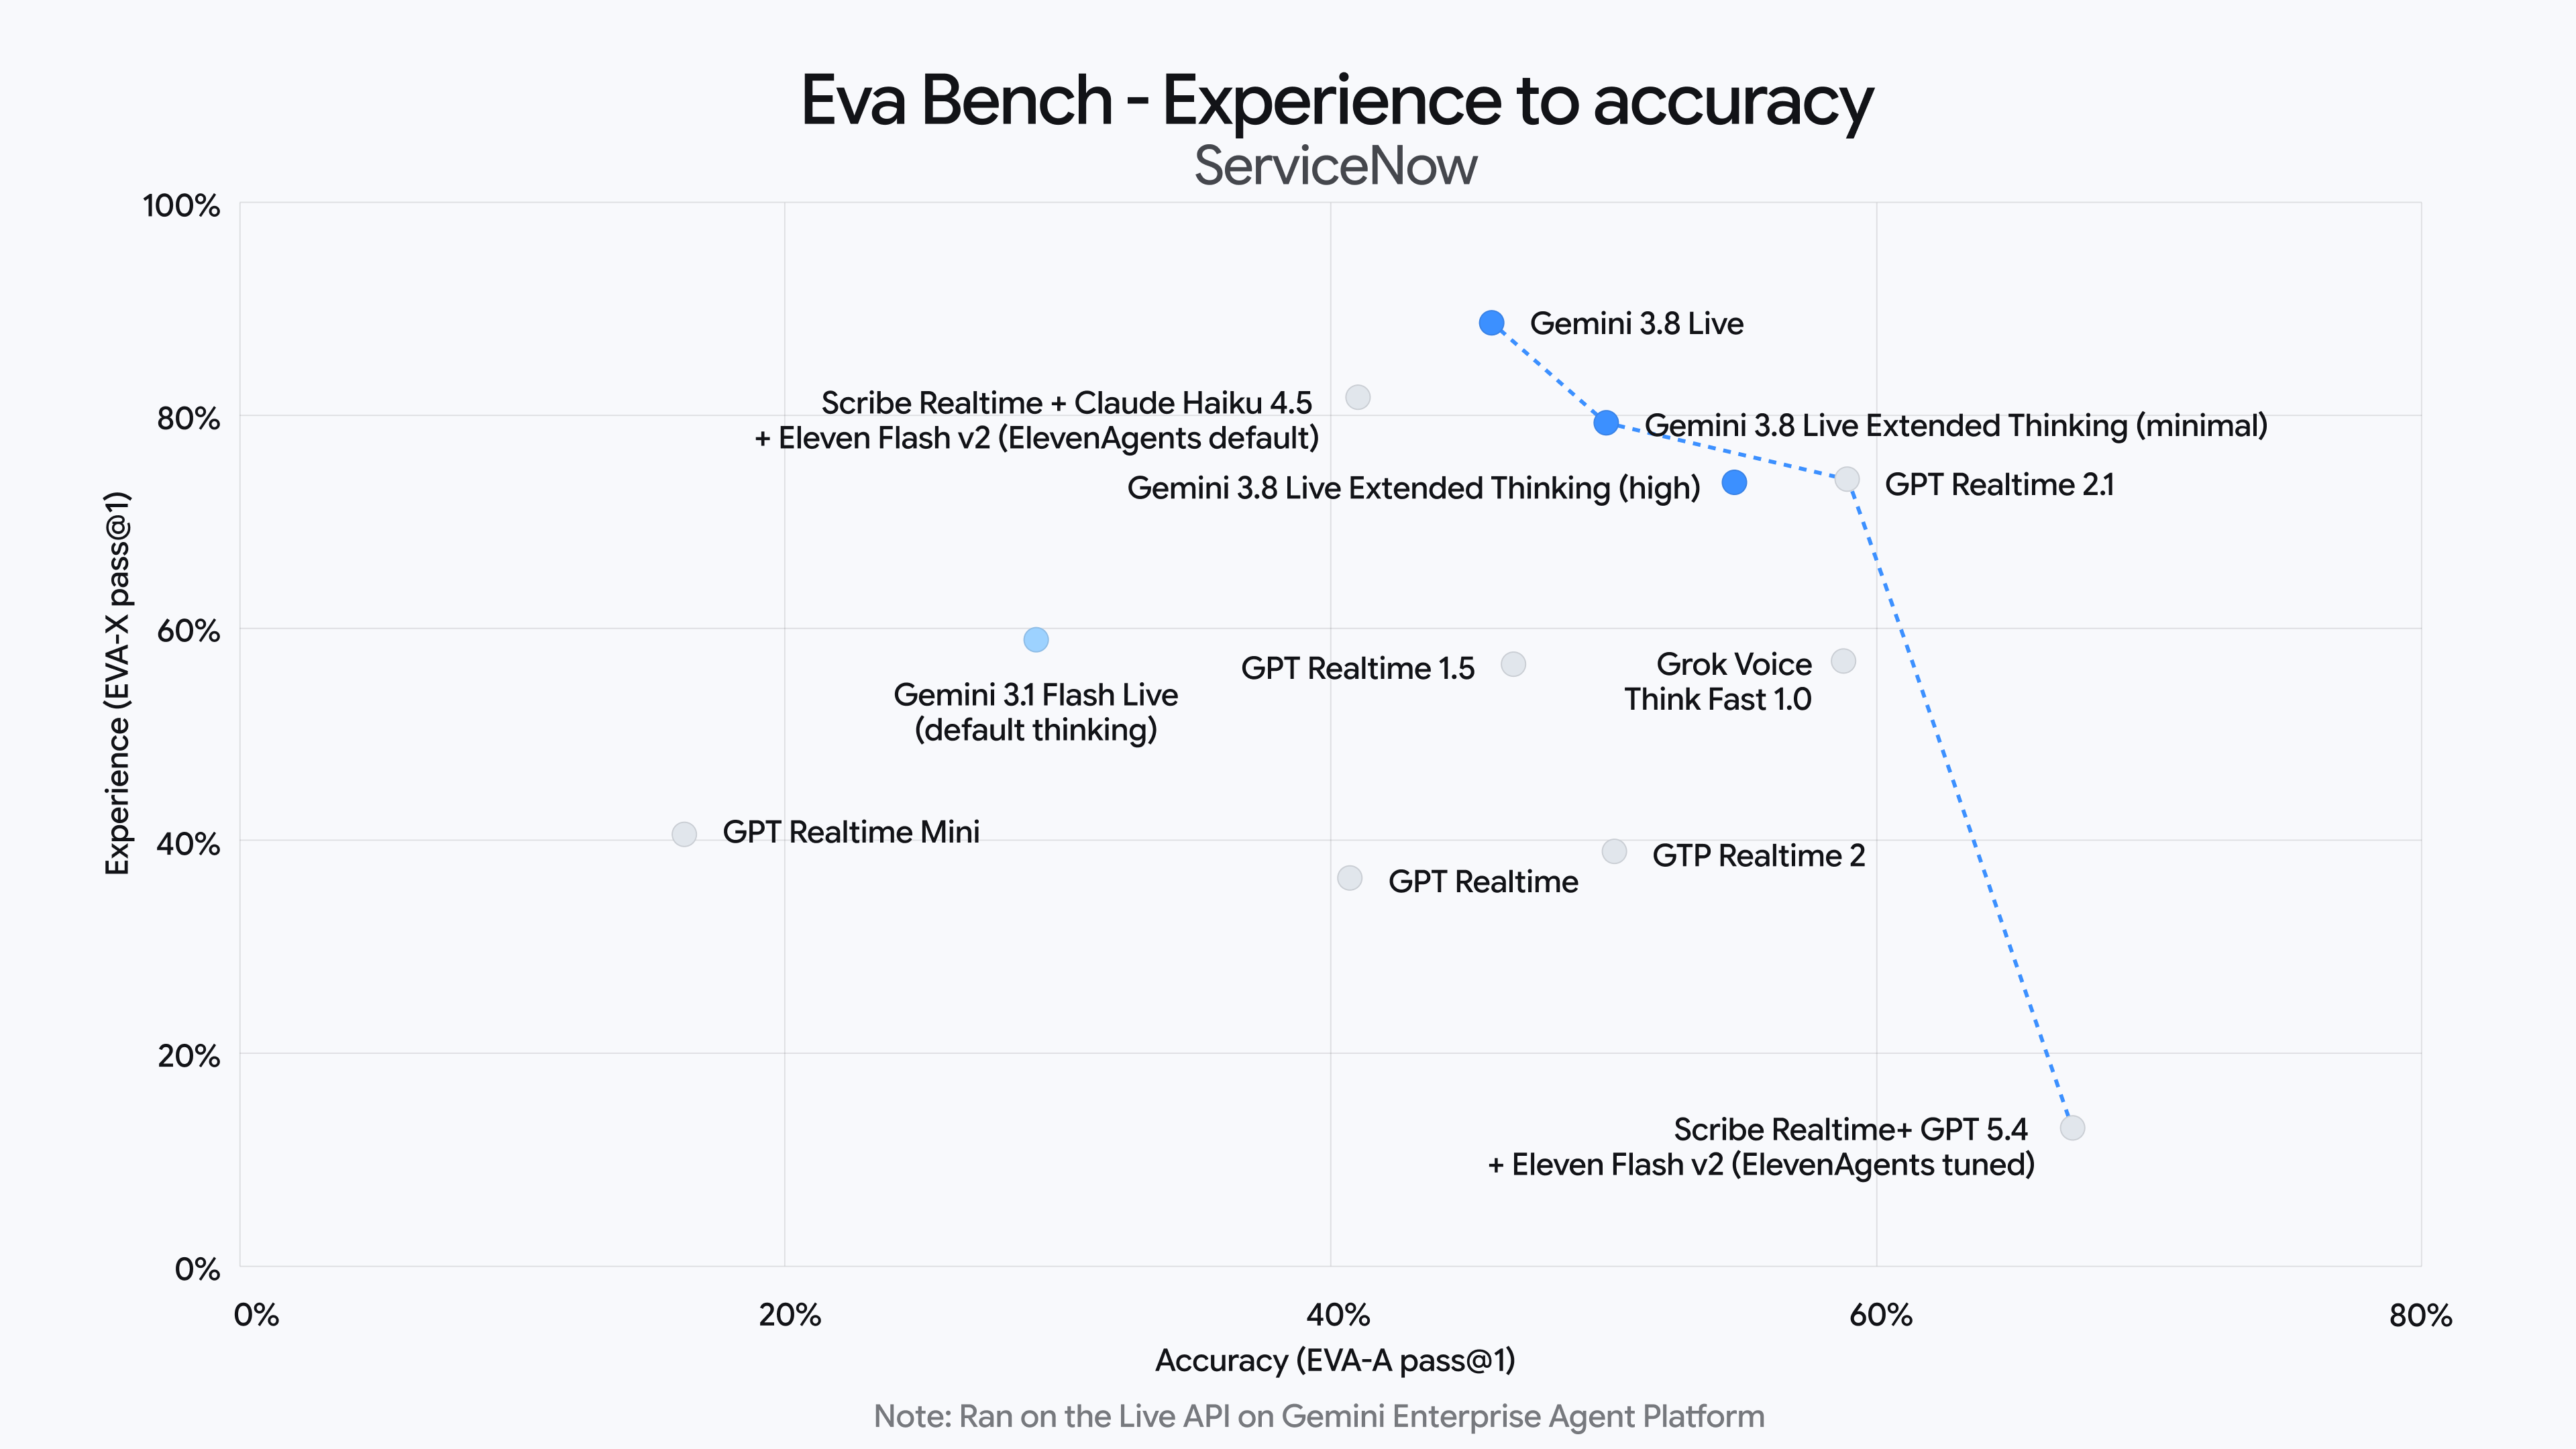
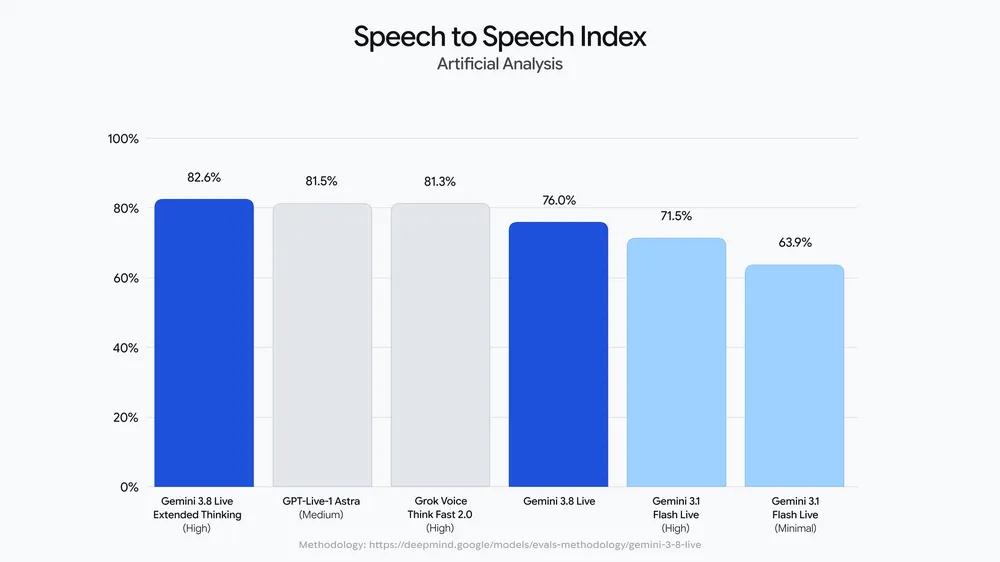
In terms of practical application, the new generation of Live series models will significantly expand the service boundaries of voice assistants. In addition to daily natural conversations, Gemini 3.8 Live and extended reasoning versions have demonstrated significantly better performance than previous versions in scenarios with high intellectual demands such as real-time step troubleshooting, complex mathematical derivation, real-time foreign language simultaneous tutoring, and multi-task streaming instruction execution, ranking first in multiple multi-modal and speech reasoning industry benchmarks.
For developers and enterprise users, Google announced that relevant model capabilities will be officially open for access through Gemini API and Google AI Studio from now on. Developers can directly call this extremely low-latency native audio API interface to quickly build next-generation full-duplex voice agent services with high-order reasoning capabilities in product forms such as intelligent hardware, customer service, real-time programming assistance, and collaborative office.
Comments